Nexusflow / athene family / text-generation
Athene-V2-Chat
Nexusflow/Athene-V2-Chat
Benchmarks
Where it scores.
Normalized 0–100 across indexed models.
Runnable variants
Pick a size.
| Precision | Format | Size | Params | File |
|---|---|---|---|---|
| FP16 / smallest | SAFETENSORS | 2.5 GB | — | model-00031-of-00031.safetensors |
| FP16 | SAFETENSORS | 3.2 GB | — | model-00030-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.5 GB | — | model-00001-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00003-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00007-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00011-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00015-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00019-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00023-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00027-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00004-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00005-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00008-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00009-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00012-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00013-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00016-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00017-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00020-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00021-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00024-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00025-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00028-of-00031.safetensors |
| FP16 | SAFETENSORS | 4.8 GB | — | model-00029-of-00031.safetensors |
| FP16 | SAFETENSORS | 5.0 GB | — | model-00002-of-00031.safetensors |
| FP16 | SAFETENSORS | 5.0 GB | — | model-00006-of-00031.safetensors |
| FP16 | SAFETENSORS | 5.0 GB | — | model-00010-of-00031.safetensors |
| FP16 | SAFETENSORS | 5.0 GB | — | model-00014-of-00031.safetensors |
| FP16 | SAFETENSORS | 5.0 GB | — | model-00018-of-00031.safetensors |
| FP16 | SAFETENSORS | 5.0 GB | — | model-00022-of-00031.safetensors |
| FP16 | SAFETENSORS | 5.0 GB | — | model-00026-of-00031.safetensors |
Sizes are file sizes, not peak runtime memory.
Raw benchmarks
The inputs.
| Source | Task | Raw | Normalized |
|---|---|---|---|
| Arena | ArenaScore | 1314.1 | 76.8 |
From the Hugging Face model card
About this model.
From the Hugging Face model card
About this model.
Athene-V2-Chat-72B: Rivaling GPT-4o across Benchmarks
Nexusflow HF - Nexusflow Discord - Athene-V2 Blogpost
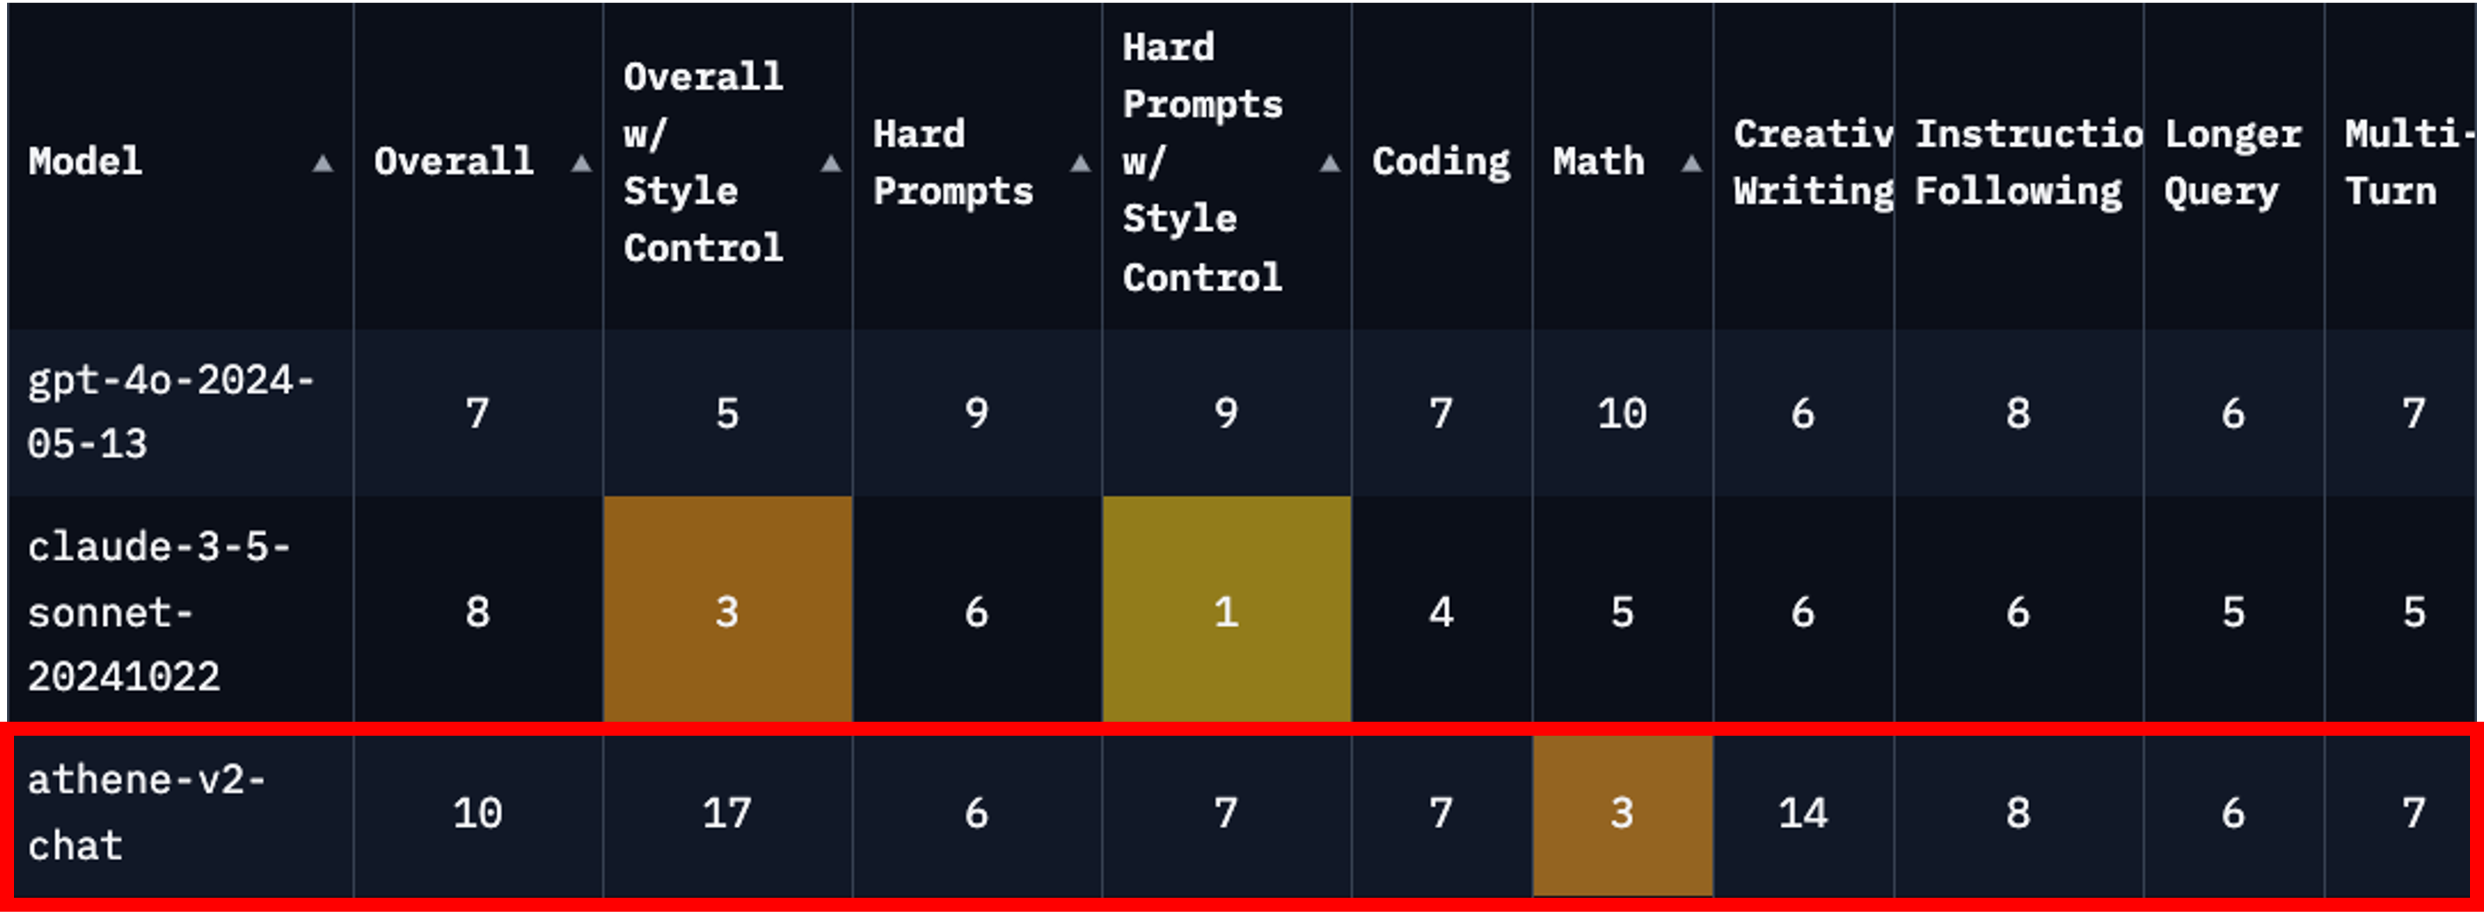
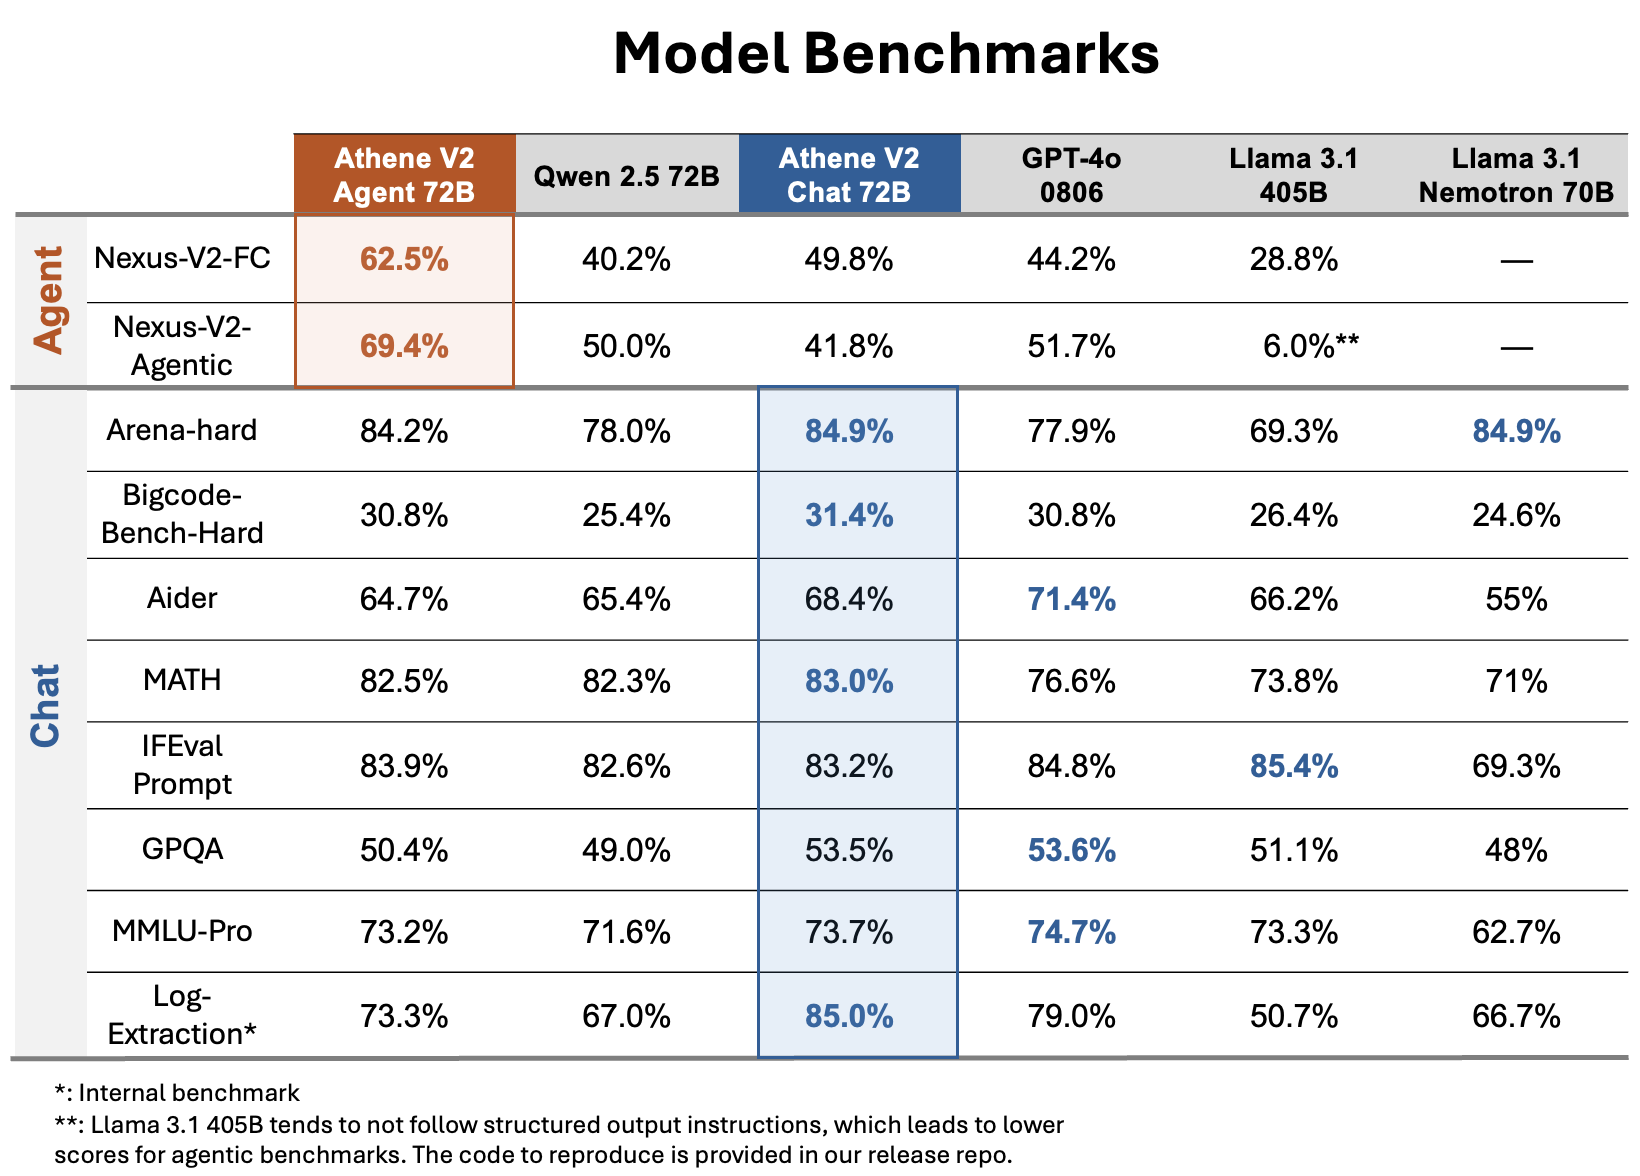
We introduce Athene-V2-Chat-72B, an open-weights LLM on-par with GPT-4o across benchmarks. It is currently the best open model according to Chatbot Arena, where it beats GPT-4o-0513 (the best GPT-4o model on Arena) in hard and math category, and is on-par with GPT-4o-0513 in coding, instruction following, longer query and multi-turn.
It is trained through RLHF with Qwen-2.5-72B-Instruct as base model. Athene-V2-Chat-72B excels in chat, math, and coding. Its sister model, Athene-V2-Agent-72B, surpasses GPT-4o in complex function calling and agentic applications.
- Developed by: The Nexusflow Team
- Model type: Chat Model
- Finetuned from model: Qwen 2.5 72B-Instruct
- License: Nexusflow Research License
- Blog: https://nexusflow.ai/blogs/athene-v2
Usage
Athene-V2-Chat uses the same chat template as Qwen2.5-72B-Instruct. Below is an example simple usage using the Transformers library.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "Nexusflow/Athene-V2-Chat"

model = AutoModelForCausalLM.from_pretrained(
    model_name,
    torch_dtype="auto",
    device_map="auto"
)
tokenizer = AutoTokenizer.from_pretrained(model_name)

prompt = "Write a Python function to return the nth Fibonacci number in log n runtime."

messages = [
    {"role": "user", "content": prompt}
]

text = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True
)

model_inputs = tokenizer([text], return_tensors="pt").to(model.device)

generated_ids = model.generate(
    **model_inputs,
    max_new_tokens=2048
)

generated_ids = [
    output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)
]

response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
Note that by adding a system prompt that encourages the model to think step by step, the model can improve further on difficult math queries and problems like counting rs in strawberry. For fairness consideration we do not include such system prompt during chat evaluation.
Acknowledgment
We would like to thank the LMSYS Organization for their support of testing the model. We would like to thank Qwen Team and the open source community for their efforts in providing the datasets and base models.