zai-org / glm family / text-generation
glm-4.6
zai-org/glm-4.6
Benchmarks
Where it scores.
Normalized 0–100 across indexed models.
Runnable variants
Pick a size.
| Precision | Format | Size | Params | File |
|---|---|---|---|---|
| FP16 / smallest | SAFETENSORS | 705.6 GB | — | model-00001-of-00092.safetensors |
Sizes are file sizes, not peak runtime memory.
Raw benchmarks
The inputs.
| Source | Task | Raw | Normalized |
|---|---|---|---|
| Arena | ArenaScore | 1424.3 | 90.5 |
| ZeroEval | AIME2025 | 93.9 | 93.9 |
| ZeroEval | GPQA | 81.0 | 81.0 |
| ZeroEval | HLE | 17.2 | 17.2 |
| ZeroEval | SWEBenchVerified | 68.0 | 68.0 |
From the Hugging Face model card
About this model.
From the Hugging Face model card
About this model.
GLM-4.6

👋 Join our Discord community.
📖 Check out the GLM-4.6 technical blog, technical report(GLM-4.5), and Zhipu AI technical documentation.
📍 Use GLM-4.6 API services on Z.ai API Platform.
👉 One click to GLM-4.6.
Model Introduction
Compared with GLM-4.5, GLM-4.6 brings several key improvements:
- Longer context window: The context window has been expanded from 128K to 200K tokens, enabling the model to handle more complex agentic tasks.
- Superior coding performance: The model achieves higher scores on code benchmarks and demonstrates better real-world performance in applications such as Claude Code、Cline、Roo Code and Kilo Code, including improvements in generating visually polished front-end pages.
- Advanced reasoning: GLM-4.6 shows a clear improvement in reasoning performance and supports tool use during inference, leading to stronger overall capability.
- More capable agents: GLM-4.6 exhibits stronger performance in tool using and search-based agents, and integrates more effectively within agent frameworks.
- Refined writing: Better aligns with human preferences in style and readability, and performs more naturally in role-playing scenarios.
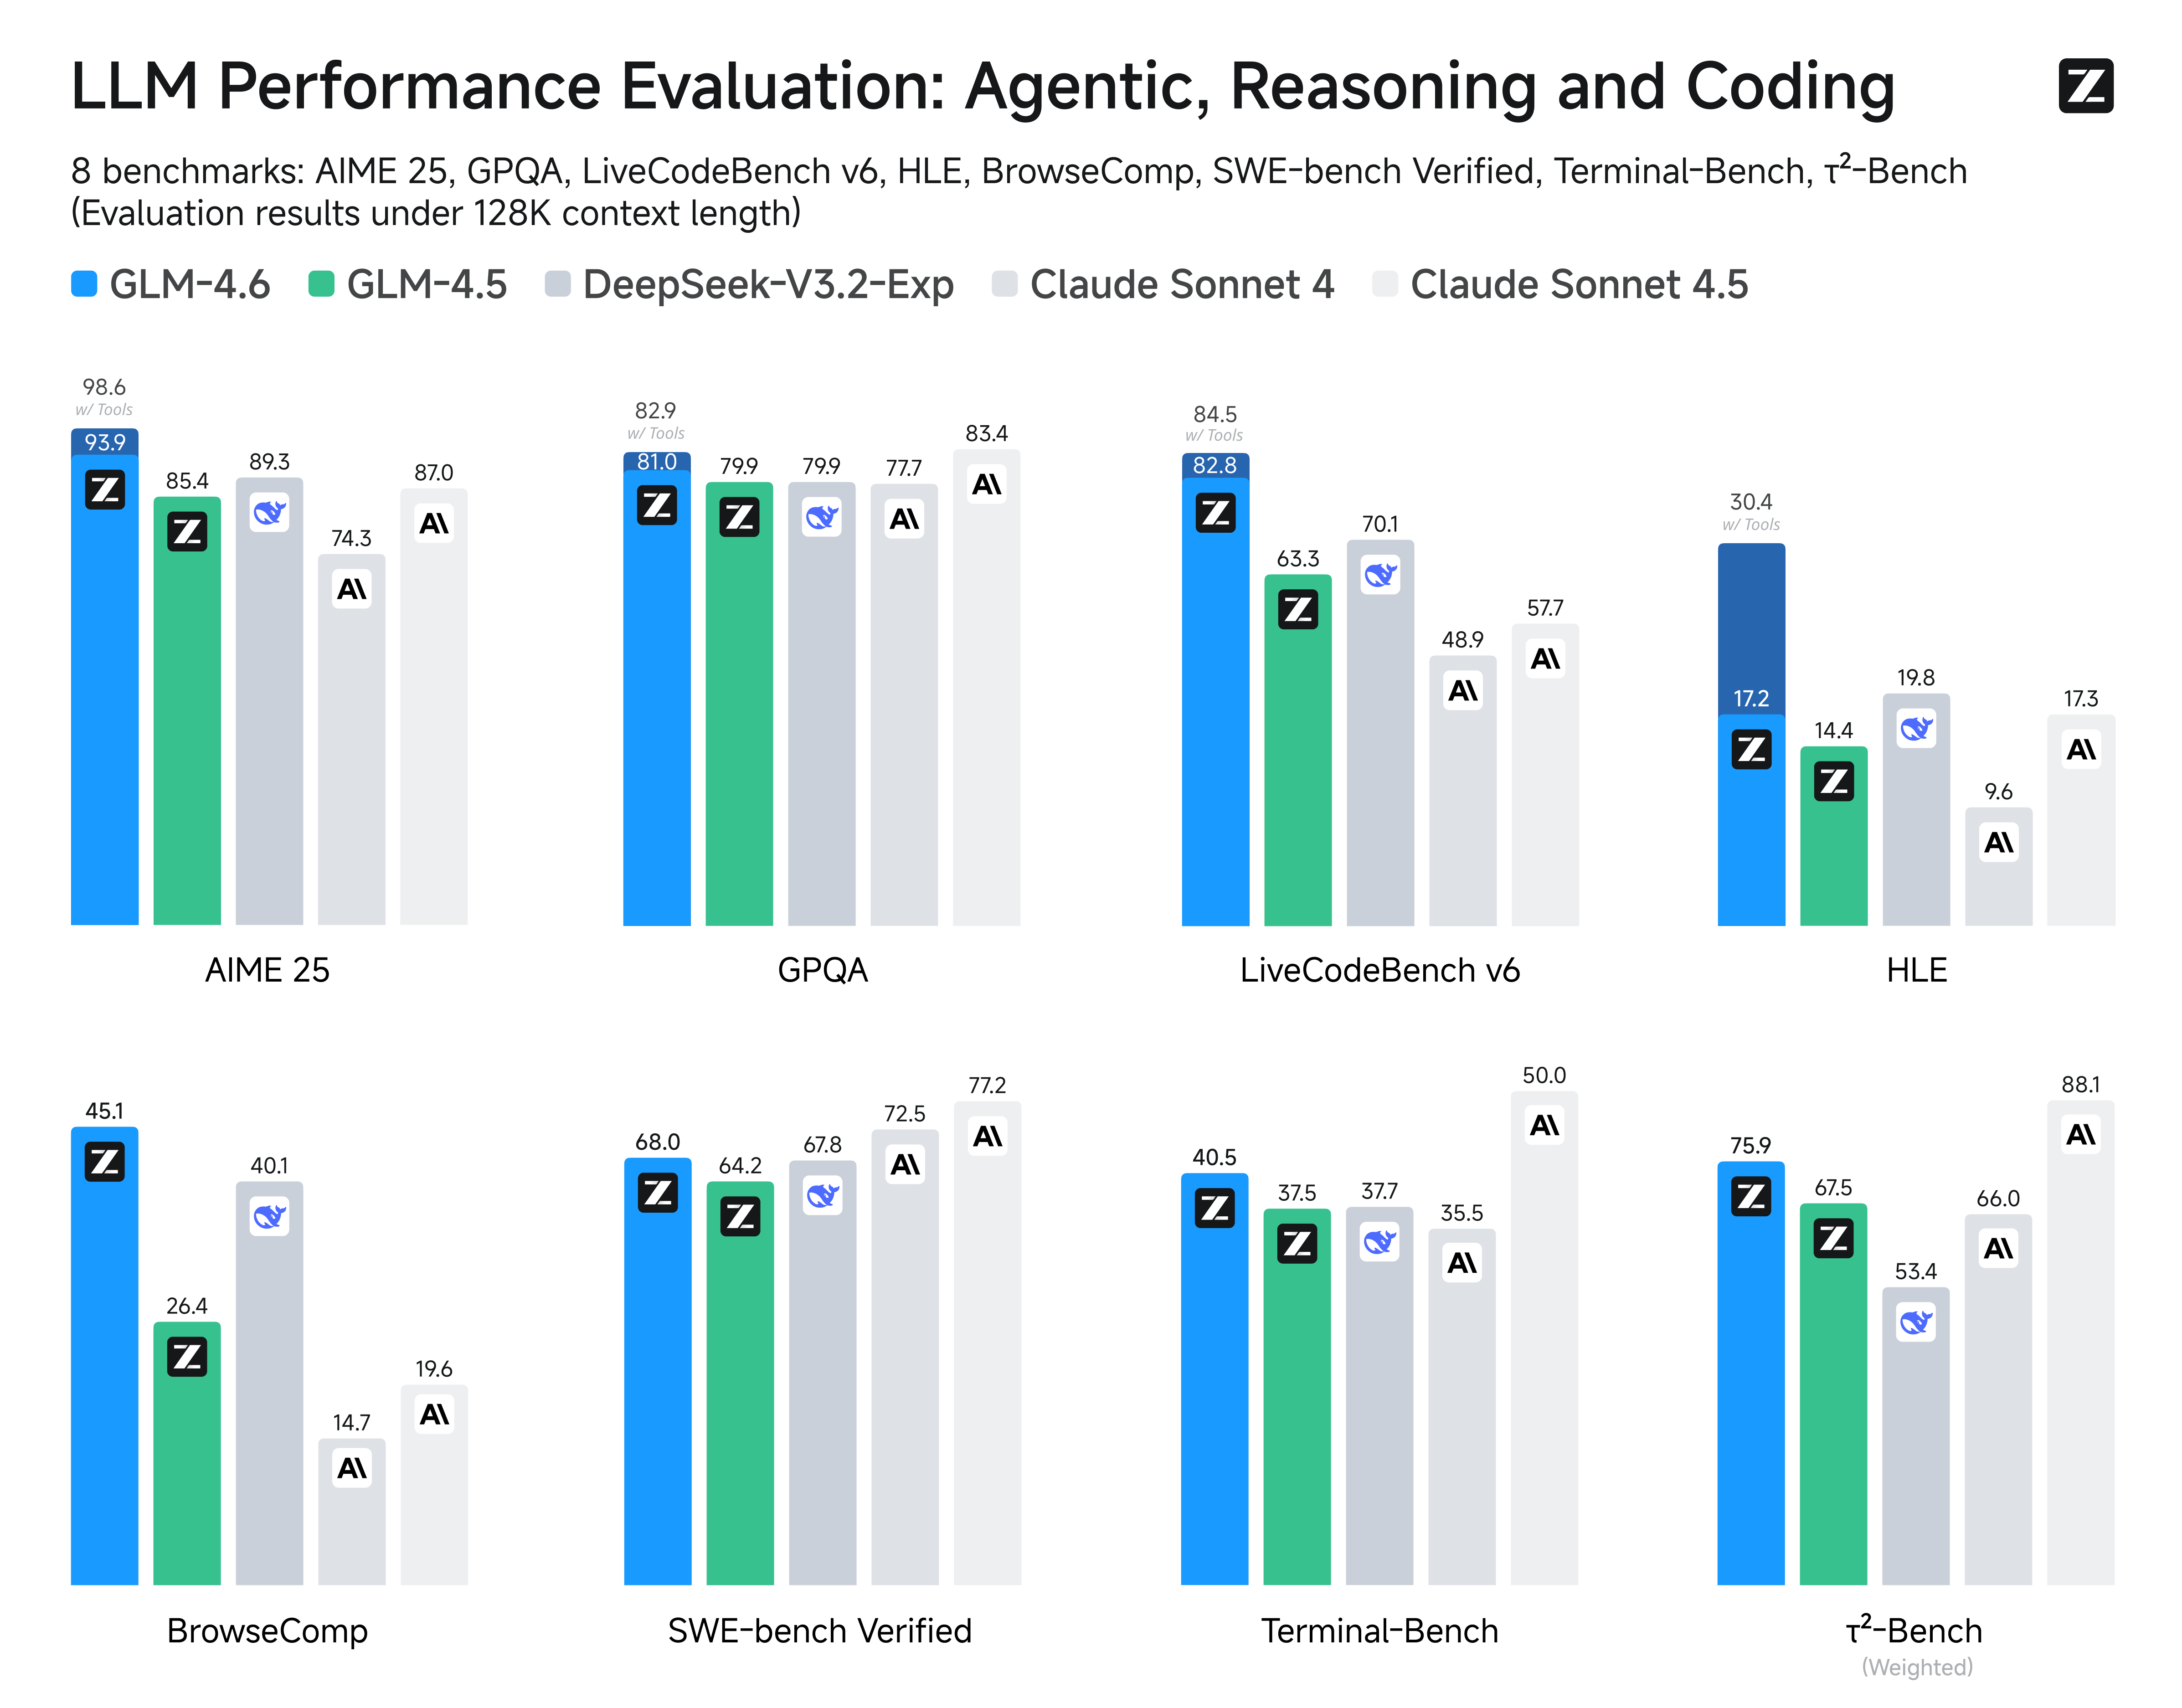
We evaluated GLM-4.6 across eight public benchmarks covering agents, reasoning, and coding. Results show clear gains over GLM-4.5, with GLM-4.6 also holding competitive advantages over leading domestic and international models such as DeepSeek-V3.1-Terminus and Claude Sonnet 4.
Inference
Both GLM-4.5 and GLM-4.6 use the same inference method.
you can check our github for more detail.
Recommended Evaluation Parameters
For general evaluations, we recommend using a sampling temperature of 1.0.
For code-related evaluation tasks (such as LCB), it is further recommended to set:
top_p = 0.95top_k = 40